The Six Controls AI Code Review Needs Before You Scale It
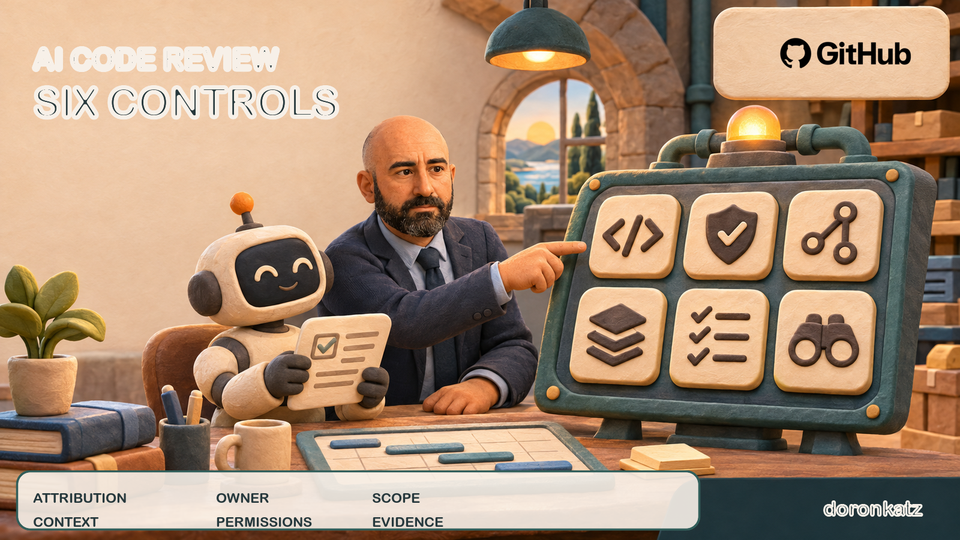
AI code review needs six controls before it needs another model.
That is the operating lesson inside GitHub's latest code-review updates. Teams can now manage selected Copilot code-review settings through REST and GraphQL APIs, from enterprise policy down to repositories. Reviews and comments can carry explicit attribution fields. A response can report its review effort and the skills, MCP servers, or custom instructions it used as sources.
Those are useful capabilities. They are not a governance system by themselves.
For a PM or TPM, the launch question is no longer only, “Does the review find useful issues?” It is also: Who authorized the review? Which repositories are in scope? What context may it use? Which credential can change the settings? What evidence would tell us that people acted on the feedback—and whether acting was the right decision?
The model writes the review. The operating contract determines whether the workflow is governable.
Here is the six-control contract I would put in place before scaling AI code review.
1. Identity and attribution
Every review, comment, configuration change, and follow-up action needs an attributable identity.
GitHub's update makes Copilot reviews and comments identifiable through explicit attribution fields. That matters because an AI-generated comment should not arrive as anonymous workflow noise. A reviewer needs to know which system produced it, under which configuration, and at what point in the pull-request lifecycle.
Attribution is necessary, but it is not proof. A source list can tell you that a skill, MCP server, or custom instruction was reported as context. It cannot prove that the context was correct, complete, or helpful. Keep identity and provenance as evidence fields, not quality labels.
Minimum control:
- Record the reviewing system and its configuration version.
- Preserve attribution on the review and each comment.
- Link the output to the pull request, repository, and review attempt.
- Make human edits and overrides distinguishable from the original output.
If the team cannot reconstruct who—or what—produced a review, the workflow is not ready to scale.
2. A named policy owner
Configuration needs an accountable owner at every level where policy can change.
GitHub separates enterprise, organization, and repository controls. Enterprise administrators can set the outer boundary. Organization administrators can manage options inside that boundary. Repository administrators can control repository-level behavior such as review effort and whether reviews use custom instructions or MCP tools.
That hierarchy is a useful product feature, but the program still needs a decision model. “The admin set it” is not ownership.
Name the person or team responsible for:
- the enterprise policy;
- organization defaults and exceptions;
- repository enrollment;
- changes to review effort or contextual tools;
- approval, billing, and maximum-effort settings that are not exposed through the same API surface.
The policy owner does not need to approve every review. The owner does need to define the rule, the exception path, and the rollback decision.
3. Repository scope
Do not turn on AI review everywhere because it worked in one repository.
Repository scope is a risk decision. A documentation site, a mobile client, an authentication service, and an infrastructure repository do not have the same failure modes. They should not inherit the same launch criteria simply because one API can address them all.
Start with an explicit allowlist. For each repository, record:
- the code and data sensitivity;
- protected paths and generated files;
- human-review requirements;
- whether draft pull requests and later pushes are reviewed;
- the permitted review-effort range;
- the stop condition that removes the repository from the pilot.
The safest default is narrow enrollment with visible exceptions. Expansion should follow evidence from the workflow, not enthusiasm for the feature.
4. Allowed context and provenance
An AI review is partly a function of the context it is allowed to see.
Custom instructions can encode repository conventions. Skills can add repeatable procedures. MCP servers can expose more tools or data. Each can make a review more relevant. Each can also widen the trust boundary.
Treat context as a governed dependency:
- inventory every allowed instruction, skill, and MCP server;
- name its owner and source;
- version changes that can alter review behavior;
- restrict access to the minimum data required;
- record what the reviewer reported using;
- define what must never leave the repository or organization boundary.
Reported provenance is a trace, not a verdict. A sampled audit still needs to compare the comment with the code, policy, and actual context available at the time.
5. Credential and permission boundary
The credential that reads settings should not quietly become the credential that changes policy everywhere.
GitHub's current boundaries are specific. Repository settings endpoints support GitHub Apps and fine-grained personal access tokens with Administration: read for reads and Administration: write for updates. Enterprise and organization settings endpoints, including the organization runner endpoint, do not support those credential types. Classic personal access tokens require repository-administrator access.
That is not an implementation footnote. It is part of the control design.
Document:
- which identity performs reads;
- which identity performs writes;
- the exact scope and level where each credential works;
- how credentials are stored and rotated;
- which changes require human approval;
- how an unauthorized or uncertain change is reconciled before retrying.
API availability does not make broad write access a sensible default. Separate observation from mutation wherever the platform permits it.
6. An evidence loop that does not confuse activity with quality
The easiest AI-review metric to collect may be the easiest one to misuse.
GitHub's repository-level usage reports now include an addressed rate: evaluated review comments that a developer acted on divided by total evaluated comments. “Acted on” can include applying a suggestion, asking Copilot to make a fix, editing the code, or replying that the fix will come in a later pull request. Comments are evaluated on the day the pull request merges, not the day the comment was posted.
That makes addressed rate a useful workflow signal. It does not make it a correctness score.
A high rate can mean the comments were valuable. It can also reflect a low-friction suggestion style, a narrow repository mix, or people responding to satisfy the workflow. A low rate can mean weak comments, or it can mean the system correctly raised difficult issues that required a different resolution.
Pair the proxy with a measurement stack:
- Activity: review runs, evaluated comments, addressed comments.
- Human response: later human change requests, overrides, and sampled disagreement reasons.
- Delivery quality: rework, escaped defects, rollback signals, and policy violations.
- Flow: review latency and time waiting for the next decision.
- Audit quality: sampled reviews where a qualified human checks whether the comment and response were actually sound.
Do not compare teams until repository scope, merge-day windows, permissions, and activity mix are aligned. An attractive percentage with a shifting denominator is not a management system.
The cross-platform pattern: agents need accountable participation
This control model is bigger than code review.
Atlassian's November Jira announcement describes agents with their own identity and clear owner, visible work, administrative guardrails, and an activity view. Atlassian's Agentic Multiplayer Protocol frames the same operating concerns around identity, attribution, scoped permissions, shared context, and auditability.
The rollout is staged: the announcement says continuous-release customers receive the features over the following weeks, bundled-release customers see them in December and January, and general availability across Jira Cloud is targeted by the end of November. That timing matters. Do not write an operating policy as if every team has the same capability today.
The useful pattern is consistent across tools:
- identity without ownership is insufficient;
- context without boundaries is risky;
- activity without outcome evidence is easy to overvalue;
- automation without a rollback owner is incomplete.
An agent can participate in delivery work. It should not become the unowned exception to the rules that govern everyone else.
A launch checklist for PMs and TPMs
Before expanding AI code review, ask the launch team to complete this checklist:
- Every review and comment has attributable identity.
- Enterprise, organization, and repository policy owners are named.
- Pilot repositories are allowlisted by risk class.
- Allowed instructions, skills, and MCP servers are inventoried and versioned.
- Read and write credentials have the minimum required permissions.
- Approval, billing, and maximum-effort controls outside the API are documented.
- Addressed rate is labeled as an activity proxy, not a quality KPI.
- Human-response, delivery-quality, flow, and audit signals sit beside the proxy.
- Exceptions, stop conditions, and rollback ownership are explicit.
- The first sampled review audit is on the calendar.
If the team cannot complete one of those lines, that is the next governance task. It is not a reason to hide the gap behind a better model.
What these controls do not prove
None of the vendor announcements cited here establishes that AI code review improves defect prevention, delivery speed, cycle time, ROI, or reviewer trust. Attribution does not prove correctness. Reported context does not prove useful context. Addressed rate does not prove a good decision.
These six controls do something more modest and more important: they make the workflow inspectable. They give the program a way to explain who configured the system, where it may run, what it may use, which permissions it holds, and what evidence would support expansion or rollback.
Audit one existing AI-review workflow against the six controls this week. Find the first blank field. Give it an owner and a date before you add another repository.
Sources
- GitHub Changelog — Copilot code review: API management and review overview updates (November 6, 2026)
- GitHub Docs — Configuring code review by GitHub Copilot
- GitHub Changelog — Usage metrics API adds code review details and addressed rate (November 5, 2026)
- GitHub Docs — Data available in Copilot usage metrics
- Atlassian Community — Introducing the Jira 2026 Autumn Release (November 3, 2026)
- Atlassian — Agentic Multiplayer Protocol
Published by
Doron Katz © 2026
Member discussion